Linear Regression in R: Fit, Check and Interpret a Model
Fit and interpret linear regression in R using a transparent teaching dataset. Check residuals, distinguish confidence from prediction intervals and avoid unsupported causal or predictive claims.
On this page
- 1. Define the outcome, predictor and purpose
- 2. Create and inspect a transparent dataset
- 3. Fit the model using lm
- 4. Interpret the intercept in context
- 5. Distinguish coefficients, uncertainty and model fit
- 6. Inspect residuals and influential observations
- 7. Separate confidence intervals from prediction intervals
- 8. Evaluate prediction on relevant new data
- 9. Report an interpretable result
- 10. Use this pre-report checklist
- A short exercise before using your own dataset
- Questions readers ask
- Official references and further reading
Linear regression in R describes how a numeric outcome is associated with one or more predictors. With a single predictor, the familiar fitted line estimates a mean outcome at each predictor value. The important work is deciding whether that line answers the question, checking how it fits and reporting uncertainty honestly.
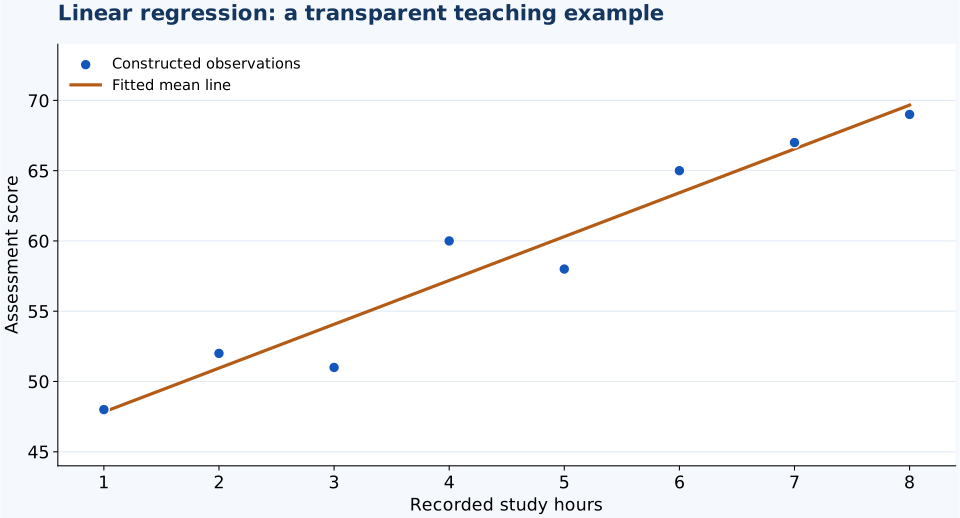
This guide uses eight constructed pairs of study hours and assessment scores. They are teaching values, not observations from actual learners. The example demonstrates the calculation; it cannot establish that extra study time causes a particular score improvement.
1. Define the outcome, predictor and purpose
Here the outcome is assessment score and the predictor is recorded study hours. One row represents a single paired observation. We want to describe a fitted association in score units, rather than only report a unitless measure of association.
If your question only concerns association strength, start with the correlation in R guide. If the predictor is a group label and the question compares means, the one-way ANOVA guide may be more directly relevant.
Separate explanation from prediction. A model used to describe a sample does not automatically predict new observations well. Decide how you will judge success before comparing many models. In real research, describe how observations were sampled and whether repeated measurements, time ordering or clustering require a different analysis.
2. Create and inspect a transparent dataset
d <- data.frame(
  hours = c(1, 2, 3, 4, 5, 6, 7, 8),
  score = c(48, 52, 51, 60, 58, 65, 67, 69)
)
str(d)
summary(d)
plot(score ~ hours, data = d,
     pch = 16, col = "#1658b9",
     xlab = "Study hours", ylab = "Assessment score")
The plot lets you inspect every observation before fitting a line. Look for curvature, unusual points and obvious subgroups. Also check whether both variables are numeric for the right reason. A column containing category codes may be stored as numbers without representing a meaningful quantitative scale.
For your own data, document missing values and measurement definitions. Do not recode a missing score as zero to make the model run. Use the reproducible R workflow to keep these decisions in a saved script.
3. Fit the model using lm
fit <- lm(score ~ hours, data = d)
summary(fit)
coef(fit)
confint(fit)
nobs(fit)
The formula places the outcome on the left and the predictor on the right. The fitted line includes an intercept by default. R’s lm reference describes the model formula and fitted object.
For these teaching values, the estimated intercept is approximately 44.7143 and the slope is approximately 3.1190. The fitted equation is therefore: predicted mean score = 44.7143 + 3.1190 × hours.
Keep the measurement units in the explanation. The slope describes about 3.12 score points per additional recorded hour within this fitted association. It does not mean a 3.12 percent increase, and it is not a guaranteed effect of changing someone’s study schedule.
4. Interpret the intercept in context
The intercept is the model’s predicted mean score when recorded hours equals zero. However, the example only contains hours from one to eight. Zero is outside that range, so a substantive claim about zero-hour learners would require information the example does not contain.
An intercept can be necessary for fitting a useful line without being a sensible standalone claim about a population. Do not remove it simply because its interpretation feels awkward. A model without an intercept imposes a different constraint and needs a justification from the question and measurement process.
If a more meaningful reference point is helpful, a centered predictor can change the intercept’s reference value while retaining the same fitted line. That is a modeling choice to explain, not a way to manufacture a more impressive result.
5. Distinguish coefficients, uncertainty and model fit
| Output | Question it helps answer | What it does not establish |
|---|---|---|
| Estimated slope | How the fitted mean changes with the predictor | A causal effect without an appropriate design |
| Confidence interval | Uncertainty about the parameter under the model | A guarantee that all future outcomes fall inside it |
| p-value | Evidence against a specified null hypothesis under assumptions | The practical importance of an association |
| R-squared | How much sample outcome variation the fitted model accounts for | Out-of-sample accuracy or model correctness |
The example R-squared is approximately 0.9382. That is a property of the constructed sample and fitted model. It does not mean the model is “93.82 percent accurate.” A model can fit its training observations closely and still perform poorly in another setting.
Read confint(fit) with the coefficient estimates rather than reducing the analysis to a significant/not-significant label. Explain the effect scale that matters for the research or operational decision.
6. Inspect residuals and influential observations
old_par <- par(mfrow = c(2, 2))
plot(fit)
par(old_par)

checks <- data.frame(
  hours = d$hours,
  observed = d$score,
  fitted = fitted(fit),
  residual = residuals(fit)
)
checks
A residual is an observed outcome minus its fitted value. Patterns in residuals can indicate that a straight-line mean relationship or another part of the model is unsuitable. Examine changes in spread, large residuals and points that combine an unusual predictor value with substantial influence.
Do not delete a point just because the result becomes more convenient without it. Check the collection record, investigate plausible errors and report justified corrections. If an unusual observation is valid, consider an explicitly reported sensitivity analysis or a model better suited to the question.
Independence comes mainly from the study design. A tidy residual plot cannot prove that repeated scores from the same learner are independent. Normal-error assumptions also matter for the usual small-sample intervals and tests; the ability to compute a line is not proof that its inferential assumptions hold.
7. Separate confidence intervals from prediction intervals
new_case <- data.frame(hours = 5)

predict(fit, newdata = new_case,
        interval = "confidence")

predict(fit, newdata = new_case,
        interval = "prediction")
The fitted value at five hours is approximately 60.31. A confidence interval concerns the estimated mean response at that predictor value. A prediction interval concerns an individual new response under the model and includes additional outcome variation, so it is wider in this example.
The official predict.lm reference documents both options. Make sure the new-data column name matches the model predictor and that any categorical levels are appropriate for the fitted model.
A prediction for twenty hours would extrapolate far beyond the observed range of one to eight. R may return a number, but the output would not validate that extrapolation. Model software does not know whether the underlying relationship changes outside the data you supplied.
8. Evaluate prediction on relevant new data
If prediction is the goal, plan a suitable validation strategy. A random train/test split can be misleading when observations are ordered over time or clustered by person or institution. The validation arrangement should resemble the way predictions will actually be used.
This eight-row teaching dataset is too small to demonstrate reliable real-world predictive performance. Do not treat a small holdout score from these values as a benchmark. In a larger project, define a meaningful error measure and compare the model with a simple baseline.
Keep preprocessing inside the validation process where it is learned from data. Using information from a test set to choose transformations, tune a model or select variables can make the reported performance overly optimistic.
9. Report an interpretable result
An illustrative report could read: “A simple linear model fitted to eight constructed pairs gave an estimated slope of 3.119 score points per recorded hour and an intercept of 44.714. Sample R-squared was 0.9382. The dataset demonstrates syntax and does not establish a causal or predictive claim about learners.”
A real report should add sampling details, units, uncertainty, model diagnostics, missing-data handling and validation results where prediction is claimed. State important limitations, including omitted variables, measurement error, dependence and the observed predictor range.
For example, prior knowledge and study quality could both relate to assessment performance. A single-predictor model does not automatically account for them. Adding more columns without a defensible design is not a substitute for thinking about the question.
10. Use this pre-report checklist
- State whether the purpose is description, explanation or prediction.
- Identify the observational unit and measurement scales.
- Inspect the data before fitting a line.
- Document missing values and all exclusions.
- Interpret slopes in the outcome and predictor units.
- Examine residual patterns and influential observations.
- Use uncertainty intervals appropriate to the claim.
- Validate predictions in a way that reflects intended use.
- Avoid unjustified extrapolation and causal language.
- Save the script, input documentation and session information.
You do not need a complex model to produce a useful analysis. A simple, well-explained result with explicit limitations is more informative than an impressive-looking equation whose data, assumptions and intended use are unclear.
A short exercise before using your own dataset
Use a separate copy of the teaching script to explore how an analysis changes. First, remove the final observation and compare the fitted slope with the original value. This is a sensitivity exercise, not permission to exclude an observation from a real study. State exactly what changed and why.
Next, draw the fitted line without looking at the summary table. Identify where predictions are too high or too low, then compare your observations with the residual output. Connecting the plot with the residual values builds a more useful understanding than memorizing the location of the p-value.
Finally, compare the confidence and prediction intervals at a predictor value within the observed range. Explain which interval answers a question about the mean and which addresses a new individual response. If you cannot explain the distinction in ordinary language, return to the prediction section before writing a results paragraph.
When moving to a real dataset, replace the teaching labels with actual variable definitions and document their units. Keep the original script so your exploratory changes are distinguishable from the analysis you intend to report. A reader should be able to tell which choices were planned and which were made after inspecting the data.
Questions readers ask
Does linear regression prove causation?
No. A fitted association alone does not identify a causal effect. Causal interpretation requires an appropriate design and assumptions.
Does an R-squared of 0.9382 mean 93.82 percent accuracy?
No. It summarizes the proportion of sample outcome variation accounted for by this fitted model. It is not an out-of-sample accuracy percentage.
What does the slope mean in the teaching example?
The estimated slope is about 3.119 score points per additional recorded hour within the fitted association. It is not a guaranteed effect of changing study time.
How do confidence and prediction intervals differ?
A confidence interval concerns the estimated mean response at a predictor value. A prediction interval concerns an individual new response under the model and includes additional outcome variation.
Can R predict outside the observed data range?
It may calculate an output, but that does not justify extrapolation. The relationship outside the observed range needs a defensible basis.
Do I need extra packages for this regression example?
No. The example uses functions supplied with a standard R installation. Record the R session and any dependencies when adapting it.
Official references and further reading
Sources checked 19 October 2026. Follow the linked official documents for current software requirements and method details. The examples are educational and do not establish results from an actual study.
Editorial update: Oxford Training and Research. Prepared with AI-assisted drafting; the original author record is retained. Worked examples are illustrative. No independent field study or specialist review is claimed.
You may also like
Data-Driven Decision Making: From Question to Action